Bounding an update’s length does not ensure that it moves toward a solution. A rotating field makes the distinction exact. Quan and colleagues analyze nonlinear preconditioning for variational inequalities and root finding, with separate conditions for forward and extragradient methods. The following bilinear game isolates why that separation matters. Dual-Space Preconditioning for Variational Inequalities and Root-Finding Problems, arXiv:2611.13916v1.
Consider the unconstrained game \(\min_u\max_v(-uv)\). Its descent-ascent operator is \(F(u,v)=(-v,u)\), with unique root \(x^*=(0,0)\). All norms below are Euclidean. For \(x=(u,v)\), write
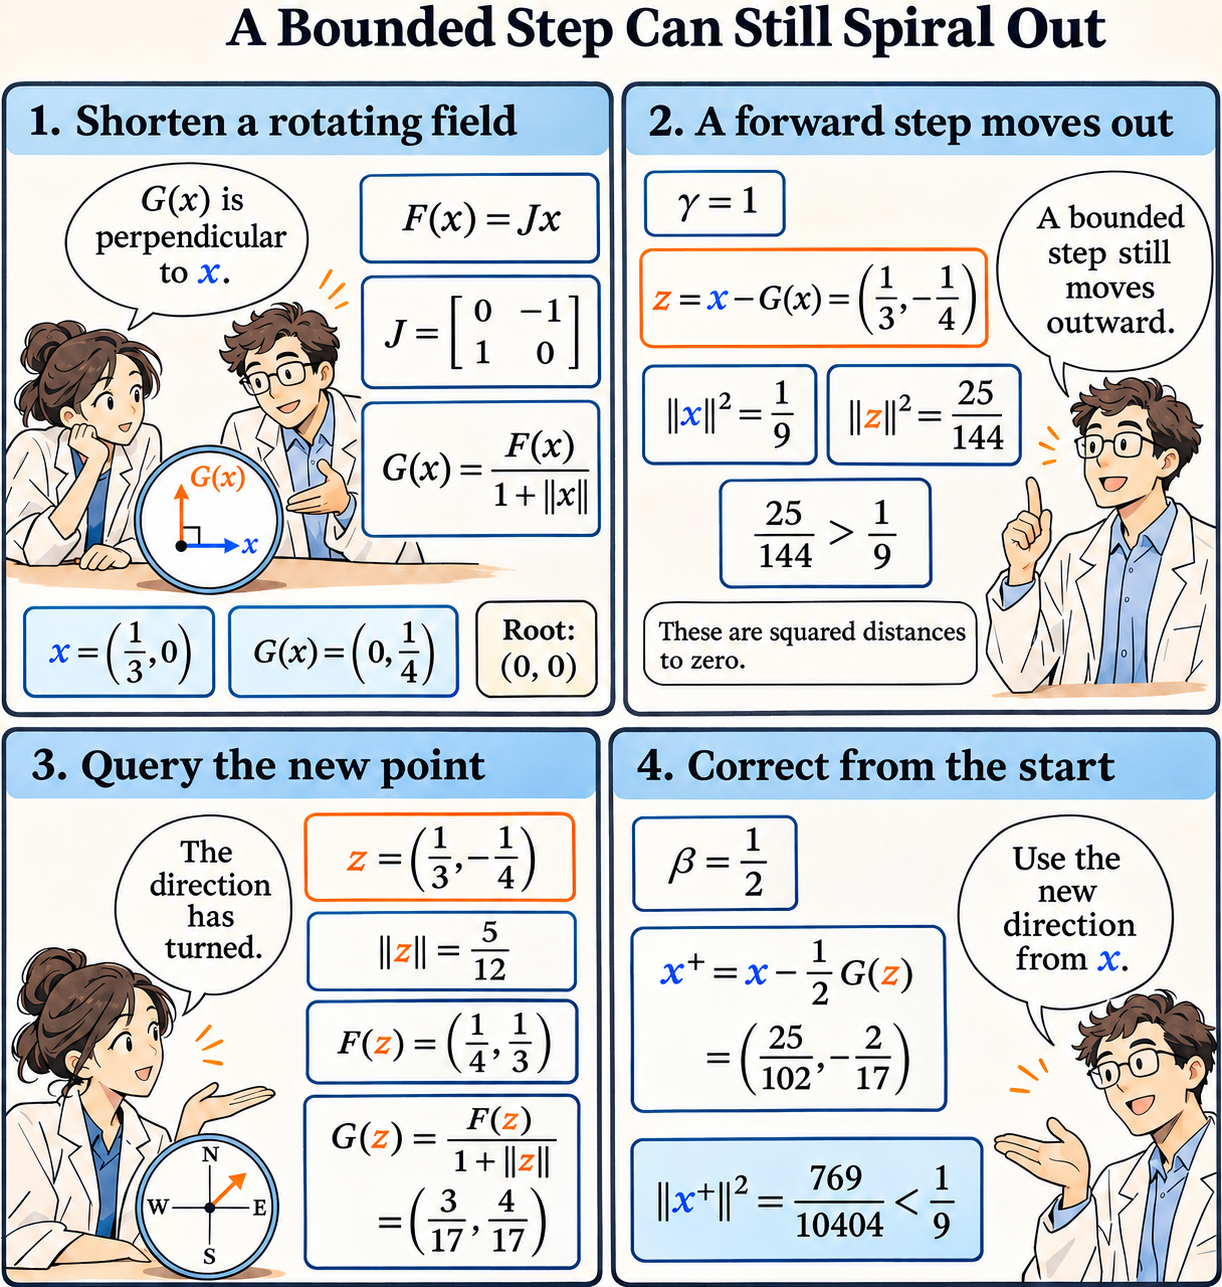
\[J=\begin{pmatrix}0&-1\\1&0\end{pmatrix}, \qquad F(x)=Jx, \qquad G(x)=\mathcal K(F(x)), \qquad \mathcal K(w)=\frac{w}{1+\lVert w\rVert}.\]Because \(J\) preserves length, \(G(x)=Jx/(1+\lVert x\rVert)\). The transformed field has the same root, has norm strictly below one, and remains perpendicular to \(x\). For a forward step \(x_{\mathrm f}=x-\gamma G(x)\), the cross term vanishes. With \(r=\lVert x\rVert\),
\[\lVert x_{\mathrm f}\rVert^2 =r^2+\frac{\gamma^2r^2}{(1+r)^2}.\]Every nonzero point moves outward for every fixed \(\gamma>0\). Repeating this update makes the radius diverge: an increasing positive radius could not have a finite limit, since the added squared-radius term would then tend to a positive constant. Each displacement is bounded by \(\gamma\), but the trajectory still escapes. The continuous flow \(\dot x=-G(x)\) instead preserves radius because \(\langle x,G(x)\rangle=0\). Neither dynamics approaches the root from a nonzero start.
There is a second geometric warning. An operator \(A\) is monotone when \(\langle A(p)-A(q),p-q\rangle\geq0\) for every pair. Our original \(F\) is monotone, since skew symmetry gives \(\langle J(p-q),p-q\rangle=0\). The transformed \(G\) is not. Take \(p=(1,0)\) and \(q=(3,4)\). Then \(G(p)=(0,1/2)\) and \(G(q)=(-2/3,1/2)\), so \(\langle G(p)-G(q),p-q\rangle=-4/3\). Normalization preserves this root and bounds the field, while losing pairwise monotonicity.
Nevertheless, \(G\) is 1-Lipschitz and satisfies the rooted Minty inequality \(\langle G(x),x-x^*\rangle\geq0\), here with equality. To check the Lipschitz claim, the Jacobian of \(\mathcal K\) at a nonzero vector of length \(s\) has radial eigenvalue \((1+s)^{-2}\) and tangential eigenvalue \((1+s)^{-1}\); its derivative at zero is the identity. These nonnegative eigenvalues also make \(\mathcal K\) monotone. Composing with the isometry \(J\) retains the Lipschitz bound. This is enough structure for the two-query calculation below, despite the failure of monotonicity of \(G\).
Use a relaxed extragradient step:
\[z=x-\gamma G(x), \qquad x^+=x-\beta\gamma G(z).\]The correction starts at \(x\) and uses the field evaluated at \(z\). Take \(x=(1/3,0)\), \(\gamma=1\) and \(\beta=1/2\). Since \(G(x)=(0,1/4)\), the exploratory point is \(z=(1/3,-1/4)\). Its norm is \(5/12\) and its squared norm is \(25/144>1/9\). Now \(F(z)=(1/4,1/3)\) and dividing by \(1+5/12=17/12\) gives \(G(z)=(3/17,4/17)\). Hence \(x^+=(25/102,-2/17)\), with squared norm \(769/10404<1/9\). The exact decrease is \(43/1156\). The second query changes direction; the relaxed correction turns an outward exploratory move into a decrease in distance to the root.
The mechanism can be proved directly in the unconstrained, zero-Minty-parameter case. Suppose \(G\) is \(L\)-Lipschitz and \(\langle G(y),y-x^*\rangle\geq0\) for every \(y\). Set \(D=\lVert x-x^*\rVert^2\), \(D^+=\lVert x^+-x^*\rVert^2\), \(a=G(x)\) and \(b=G(z)\). Expanding the correction and using \(x-x^*=z-x^*+\gamma a\) gives
\[\begin{aligned} D^+&\leq D-2\beta\gamma^2\langle b,a\rangle +\beta^2\gamma^2\lVert b\rVert^2\\ &=D-\beta\gamma^2\bigl[ \lVert a\rVert^2+(1-\beta)\lVert b\rVert^2 -\lVert a-b\rVert^2\bigr]\\ &\leq D-\beta\gamma^2\bigl[ (1-\gamma^2L^2)\lVert a\rVert^2 +(1-\beta)\lVert b\rVert^2\bigr]. \end{aligned}\]The last line uses \(\lVert a-b\rVert\leq L\lVert x-z\rVert=\gamma L\lVert a\rVert\). Thus \(0<\gamma\leq1/L\) and \(0<\beta<1\) yield a distance decrease of at least \(\beta(1-\beta)\gamma^2\lVert G(z)\rVert^2\). Summing over updates and dropping the nonnegative final distance gives
\[\min_{0\leq k\leq N}\lVert G(z^k)\rVert^2 \leq\frac{\lVert x^0-x^*\rVert^2} {\beta(1-\beta)\gamma^2(N+1)}.\]For our starting point and parameters, the right-hand side is \(4/[9(N+1)]\). This controls the best transformed residual among the query points. It does not assert a last-iterate rate for the original residual at \(x^N\).
This specializes the paper’s P-CEG+ method. Theorem 3.11 assumes a continuous monotone isotropic preconditioner with positive scaling, a Lipschitz transformed field, and a weak Minty inequality for that field plus the constraint normal cone. Our example has \(C=\mathbb R^2\), \(L=1\) and Minty parameter zero, so \(\gamma=1\) is permitted. Its forward failure does not contradict the separate forward theorem, which requires generalized cocoercivity absent here. Theorem 3.11, forward-method conditions.
Indeed, compare a nonzero \(x\) with zero in that cocoercivity condition. Its right side is \(\langle F(x),x\rangle=0\), while the term multiplied by a positive constant is \(\langle F(x),G(x)\rangle=r^2/(1+r)>0\). No positive constant can satisfy that inequality for this rotation.
Sampling adds a distinct issue. An unbiased estimate of \(F\) need not remain unbiased after nonlinear preconditioning. For an exact scalar illustration, let an oracle return zero or two with equal probability. Its mean is one, but \(\mathbb E[\mathcal K(\widetilde F)]=1/3\) while \(\mathcal K(\mathbb E[\widetilde F])=1/2\). The paper’s stochastic theorem controls this bias using growing batches: a horizon \(T\) uses \(\lceil\sqrt T\rceil\) samples at the first query and \(T\) at the second. Theorem 3.17.
My research judgment is to evaluate preconditioning and query geometry separately. Report the original residual as well as its transformed version, and compare methods at the same oracle-call budget. In this toy, \(\lVert F(x)\rVert=r\) while \(\lVert G(x)\rVert=r/(1+r)\), so their numerical scales differ even at the same point. For a learned game, test whether the rooted inequality actually holds in the region visited, and measure the bias after transformation at practical batch sizes. Bounded updates alone establish neither of those properties. The useful contribution of the framework is a way to state the missing conditions precisely; the rotating example shows why those conditions matter.
The comic was created with AI.